First I should apologize for any slop in this post, my own knowledge on the subject is limited so I had Opus investigate this.
But in short we've had on more than one occasion now experienced that we cannot login to Proget, when we try to access the front page (root url) we only get 500. Buuut the /health endpoint is happy go lucky and returns that everything is ok. This is a little tedious since we show the /health endpoint on our dashboards and also use that for automated restarts :p
So this is what Opus found on the issue after we couldn't connect again this morning.
Product/Version: ProGet 2025.25 (Build 11) — proget.inedo.com/productimages/inedo/proget:25.0.25, Linux container
Hosting: Azure App Service (single instance, Always On)
Database: Azure SQL Database, Standard S0 (10 DTU)
Summary
Intermittently, all web requests start failing with HTTP 500:
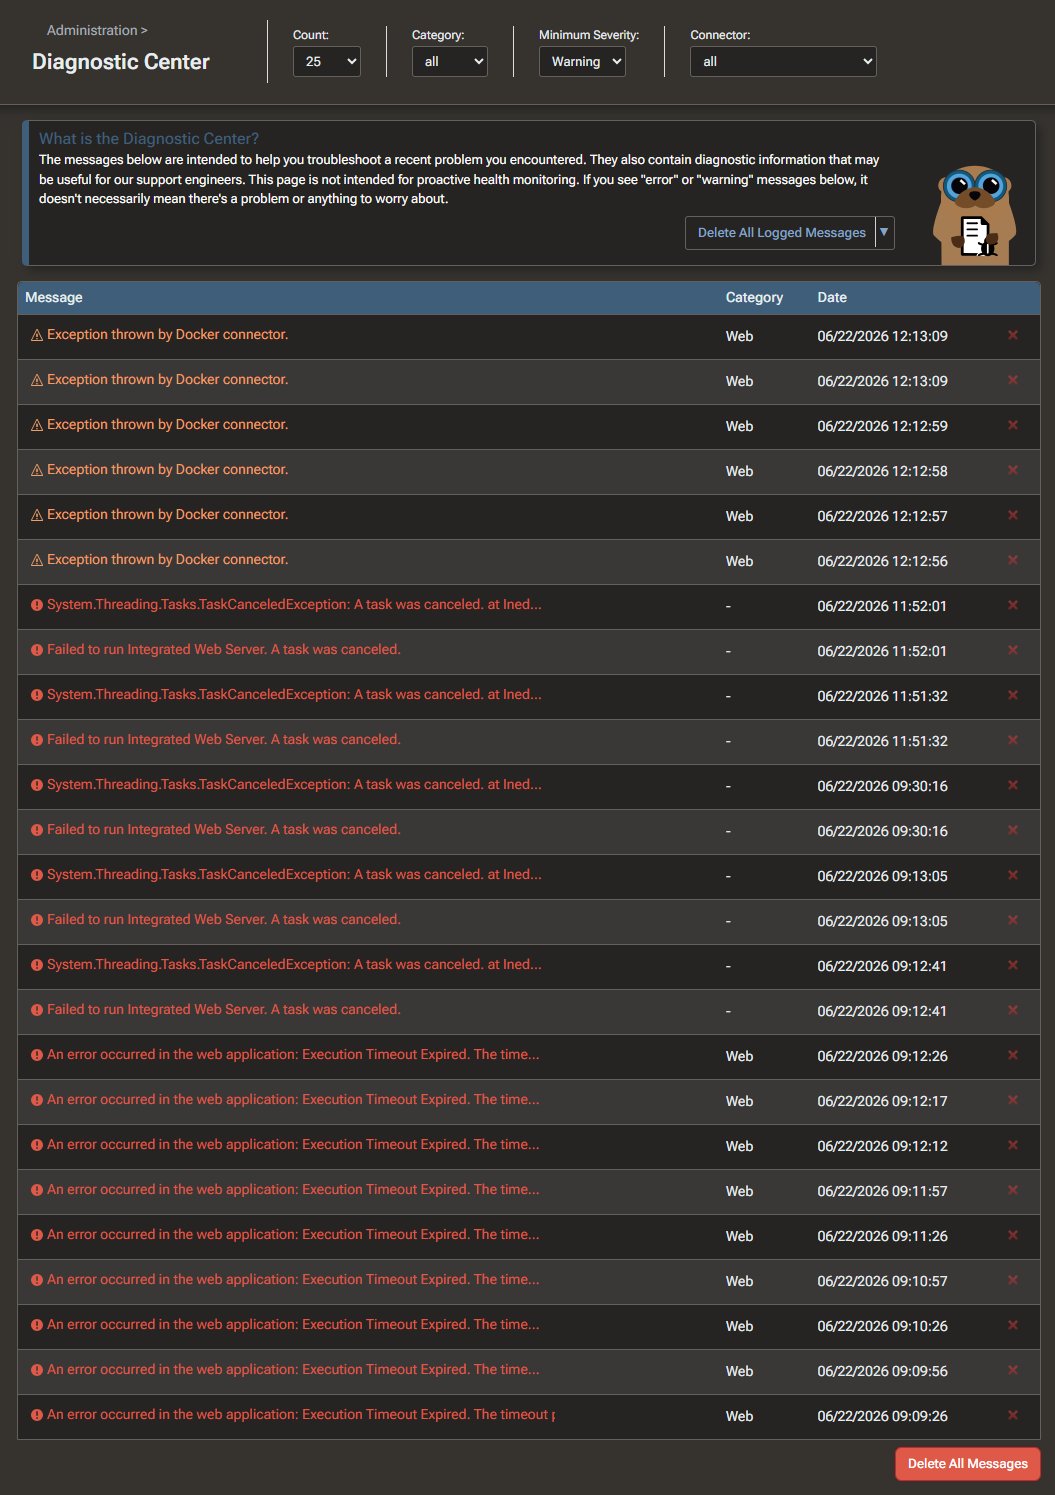
An error occurred in the web application: Execution Timeout Expired. The timeout period elapsed prior to completion of the operation or the server is not responding.
This affects both the web UI (GET /) and the Docker registry API (GET /v2/...). Once it starts, it does not self-recover; only a container restart fixes it.
Key observation — it's not the database
During the outage:
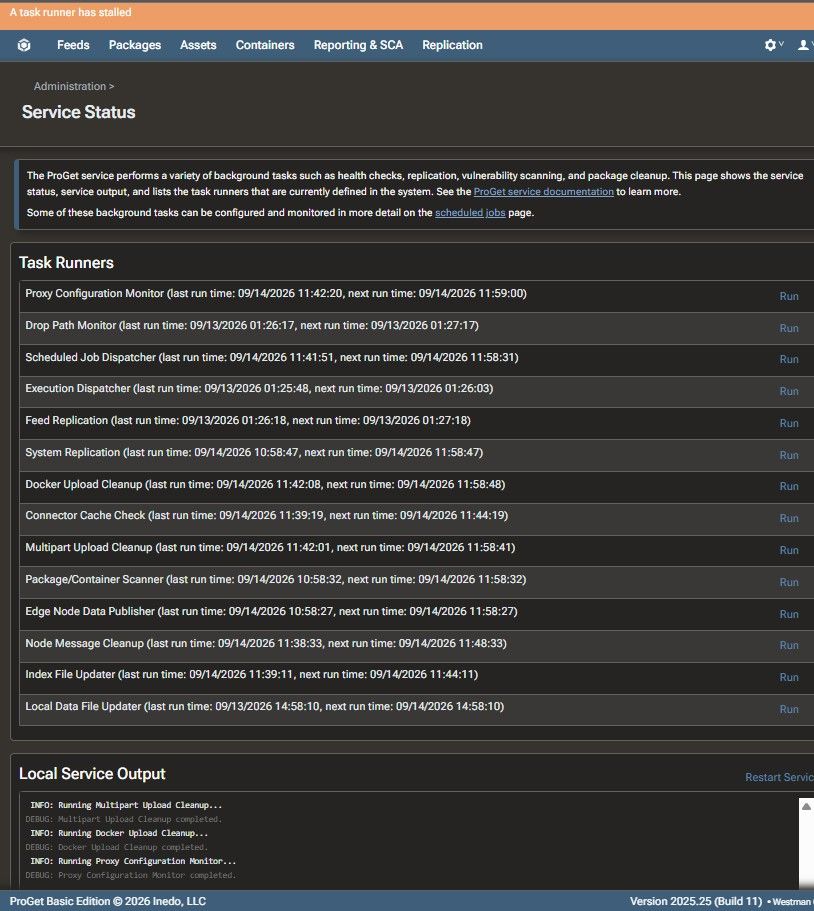
- ProGet's scheduled background tasks keep completing successfully every ~15s the entire time (Execution Dispatcher, Feed Replication, Drop Path Monitor, Node Message Cleanup, etc.). So DB connectivity clearly works.
- /health returns 200 with databaseStatus: OK, serviceStatus: OK, licenseStatus: OK.
- The Azure SQL database is idle and healthy: ~0% CPU/DTU, ≤2% workers, 0 deadlocks, 0 failed connections, ~1 session.
- The 500s return in ~3–25 ms, not after the 30s command timeout — which suggests a faulted pooled connection is being reused and rejected immediately, rather than an actual query timing out.
Only the web-request path is affected; background tasks (presumably a separate connection path/pool) are fine.
Timing / pattern
Onset is reliably around 00:00–00:05, coinciding with the burst of scheduled tasks firing at midnight. Most nights it produces a few hundred errors and recovers on its own; occasionally it wedges and stays broken for hours until restarted. Example daily 500-count (UTC): 18/6: 361, 19/6: 292, 20/6: 291, 21/6: 305, 22/6: 1177 (never recovered).
Representative log excerpt
00:01:01 Request finished GET /health - 200 648 application/json
00:01:09 An error occurred in the web application: Execution Timeout Expired. ...
00:01:09 Request finished GET / - 500 0 - 12.8ms
00:01:10 Execution Dispatcher completed. <-- background DB query OK at same moment
Opus interpretation
A transient SQL connection interruption (possibly during the midnight task burst, or an Azure SQL idle/reconfiguration disconnect) leaves a connection in the web-request pool in a faulted state. ProGet keeps reusing that pool, so every subsequent web request fails instantly with "Execution Timeout Expired," while the separately-pooled background tasks are unaffected. A restart clears the pool and restores service.
Workarounds for now
- Added ConnectRetryCount=3;ConnectRetryInterval=10 to the SQL connection string.
- Azure App Service auto-heal: recycle the app on ≥50 HTTP 500s in 5 minutes.
If required I can provide more information or logs :)
Cheers
Carl
 yep that seems to have solved it :) simple enough ;) Thanks!


 So there seems to be some issue with 25.0.10