Welcome to the Inedo Forums! Check out the Forums Guide for help getting started.
If you are experiencing any issues with the forum software, please visit the Contact Form on our website and let us know!
 A
Offline
Posts
-
RE: ProGet issue with metadata API for PyPi packages
-
RE: ProGet cannot correctly generate valid Release-File- and Package-File-Url for the Debian feed if the distribution contains slashes.
Hi @geraldizo_0690,
We haven't dug in just yet. We're assuming there's a long-standing issue with the URL Generator (as you mention), but it's not so straight-forward and seems to require a code change, etc.
We plan to get it in an upcoming maintenance release and will update as soon as we know which one specifically. In the meantime, I'd make sure you're able to upgrade to the latest version (i.e. ProGEt 2026).
Thanks,
Alana -
RE: ProGet Basic: what counts as an "active build"?
Hi @msicc ,
I would definitely budget for ProGet Enterprise, as you 100 devs is generally where a load-balanced setup really starts to make sense. It depends on so many factors, but a handful of simultaneous package restores can yield thousands of simultaneous requests by machines more powerful than a typical ProGet server (i.e. developer workstations), each which generally has to reach to connectors.
That basically leads to a DDoS against your server. See How to Prevent Server Overload in ProGet to learn more.
As for active builds,
- a build is an entry under SCA > Projects > Builds; typically one build per CI run, but you might do more
- only the first 1000 active builds are analyzed; so everything else will show as inconclusive
- you can configure different stages to automatically archive other builds upon promotion; this is what we recommend
To estimate, I would do a multiple of your active, nonlibrary projects. It's certainly feasible to have multiple active builds per project (e.g. one in build stage, one in testing, another in production), but a lot of that depends on your configuration.
Hope that helps,
Alana -
RE: [ProGet] Incorrect package publish date affecting policies
Hi @amy.j ,
If the package is already cached in ProGet, then the publish date is already set. So, i would make sure to delete the package and try it again.
Otherwise, can you share more specifics? That way we can create a reproduction case.
Thanks,
Alana -
RE: [ProGet] Feature Request/Inquiry: Feed settings when creating using PGUtil/API
@Nils-Nilsson thank you so much!
We've published a new version of
pgutilwith these commands added :) -
RE: GitHub Packages
Hi @bobmaurer ,
We recommend to import those packages into ProGet and publish to ProGet going forward.
That keeps ProGet as the source of truth for your artifacts, reduces a lot of network traffic, makes it easier for developers to not worry about multiple sources, and eliminates a lot of possible headaches later with configuration/outages/authentication./etc. Much simpler this way.
Best,
Alana -
RE: Bug: API keys written to the error log in cleartext when using ?key= auth
Hi @brad.zinser ,
This is expected behavior across our products... both the Diagnostic Center and Native API require system/admin-level access, so it's not exposing any information administrators can't already easily see.
Note that, you can also see the API key exposed in standard HTTP access logs as well if you pass via the query string, so the X-ApiKey header may be better anyway.
Thanks,
Alana -
RE: Proget Docker Documentation Postgresql
Hi @a.sieger ,
I would push back on that "hard requirement" because it doesn't make any technical or business sense, and will only lead to support headaches just like this.
There is something wrong with your PostgreSQL server configuration, perhaps permission related, that's causing the database to not be created. The error cannot be logged in the database because it doesn't exist.
I would delete the database and start again, but verify you've created the database exactly as specified using the exact version supported:
https://docs.inedo.com/docs/installation/postgresql#external-postgresThings like improper locales will cause errors.
Then, don't run ProGet detached (i.e. ommit
-d) so you can get the console logs. That's where you will see database errors. You can also run theupgradedbcommand instead:
https://docs.inedo.com/docs/installation/linux/installation-upgrading-docker-containers#upgrading-the-database-only-optionalPlease let us know what you find!
Hope that helps,
Alana -
RE: Proget SQL Express support
@forbzie22_0253 yes it's supported, but please note we are moving away from SQL Server to PostgreSQL, so you should consider migrating (Admin > Database)
-
RE: Proget Docker Documentation Postgresql
Hi @a.sieger ,
Please note that we do not recommend an external PostgreSQL database. It performs slower, costs more to maintain, has a higher chance of outages, and tends to cause support headaches down the line. The database primarily stores package metadata and application configuration, doesn't take up much disk space, and it's not the business data that your DBAs would own.
That being said if you really insist on using one, then please refer to the Database Connection String section on the page you linked.
For the non-embedded PostgreSQL database backend, you will need to specify a «inedo-product»_POSTGRES_CONNECTION_STRING environment variable instead.
So you need to use
PROGET__POSTGRES_CONNECTION_STRINGThanks,
Alana -
RE: Unlisted NuGet versions still returned by ProGet V3 flatcontainer index — restore tries to download unavailable version
Hi @daniel.mccoy_4395 ,
Actually, developer experience is a big reason we don't recommend using Download Blocking. A
400error provides no real context. Developers can see something is wrong, but not how serious it is or what to do next.First and foremost, an unlisted package should not be noncompliant. An author may decide to unlist their package for any number of reasons, including simply not wanting too many versions to show up in a list.
This would mean that, all of a sudden, a build deployed to production can suddenly be considered as noncompliant just because an open source author arbitrarily flipped a switch on NuGet.org. That's not to say you should ignore the unlisted flag, but you should definitely not put it at the same categorization as a GPL3 license or severe vulnerability.
"Compliant with Warning" could be a more appropriate status here, but keep in mind that developers swill naturally upgrade dependencies as they do platform updates, so it may not even be worth worrying about. Especially if it leads to constant warnings -- in that case, warnings become meaningless.
Noncompliant packages should be rare for the same reason. If noncompliant can be determined by an OSS author's whims, then it really caries no meaning and no one (especially your developers) will understand/appreciate what it means.
As for the workflow to use, we recommend running
pgutil builds scanwhen that pull request is run. That will not only put the build in ProGet, but it will produce a text report with warnings or noncompliant packages. A ProGet login is not required.If there are Noncomplaint packages or warnings, the developer can then comment on the PR why it's nothing to worry about. If it's always the same package/issue ("we cannot upgrade from this 5-year old library and replacing it would be a substantial effort"), then you can formalize that as an exemption.
The advantage to this workflow is that, if a deployed build later becomes noncomplaint (typically due to a vulnerability), then you can decide how and when to address it. The wrong time to address noncomplaint packages is "the next time a developer happens to open this project".
Overall, what you want to avoid is having developers load a project for what should be a trivial change and then have to upgrade dependencies because it produces pointless warnings/errors. That will just create a "constant upgrade" mentality. That leads to constant regressions and constant headaches for testers or end-users, who have to deal with strange and unexpected errors from library upgrades.
Hope that helps,
Alana
-
RE: Bug: "Download Contents as Zip" is always a 22 byte empty zip file
Hi @rcpa0,
It's hard to say, but maybe it has something to do with how the package file / archive was created.
Can you share the file or a reproduction case?
Thanks,
Alana -
RE: Interacting with releases from otterscript, especially from within a scheduled job
Thanks for clarifying; it got a little distracting with the desire to have PR cleanups and specialized variables! We also see a lot of anti-patterns in Git repositories, such as using PRs for workflows, because that's how open source projects tend to work.
Anyway, it sounds like you figured it the first part, which is to set the monitor to just create a build with a specific pipeline (e.g. "Feature Branch" pipeline).
The next step, just use a retention policy that targets builds that have completed the pipeline. For example:
-
RE: Interacting with releases from otterscript, especially from within a scheduled job
Here is the standard practice / pattern that we support for Feature Branches:
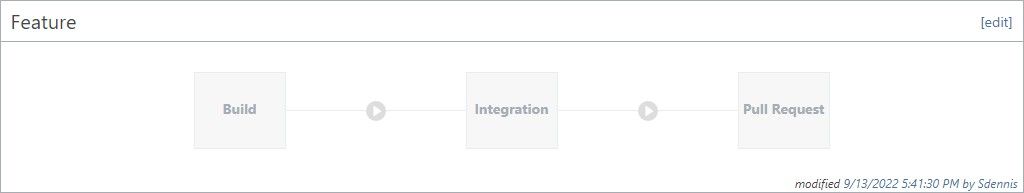
The idea is that developers start by creating a well-named feature branch (i.e. following a strict naming standard), adding commits to it, testing it, and then finally submitting a pull request for it. See our Feature Branches article to learn more about this workflow, including how retention rules can be configured.
In other words, the Pull Request comes only once the branch is ready (validated) for merging, and BuildMaster is submitting (or facilitating) that request. We take the term literally ("a request to pull the changes from the branch into into the master"):
- The branch owner is responsible for creating a "mergeable branch" and submitting that for review; a KPI here is is submitting timely/acceptable requests
- The master owner is responsible for promptly reviewing the request, then merging, closing, and deleting the branch; a KPI here is timely review/merging
In this workflow, there is no need for "commit verification" before submitting a PR. That's the responsibility of the branch owner, and they will have already done that before submitting.
I am aware that others do not use Git repositories this way, but our tooling is a generally opinionated. For example, we consider "pull requests as a backlog" as an anti-pattern for several reasons, but mostly that it's an inappropriate tool for work item management and lacks any semblance of prioritization and related feature. Issue tracking is appropriate for backlog tracking. So thaht's why there's not first-class support for it in BuildMaster.
All this said, I don't think the "Feature Branch" workflow is what you're describing. I don't quite understand it, but long story short... if it doesn't really fit into one of our use cases, so it's isn't something that's going to be easy to configure in the software - and you'll likely need to start customizing with your own Extension.
Instead, we recommend to just adjust the workflow.
Thanks,
Alana -
RE: [ProGet] Feature Request: Enable creating 'Feed & Project Groups' using API and/or PGUtil
Hi @Nils-Nilsson ,
We'll implement something like Scenario B, which mirrors how the UI handles it and is the easiest to implement:
pgutil feeds create --name=myfeed --type=NuGet --group=mygroupWe'll also target this for July 24th's release, and ship via PG-3338.
Thanks,
Alana -
RE: [ProGet] Feature Request: Expand which fields are settable when creating a Project using API/PGUtil
Hi @Nils-Nilsson,
Sorry on the slow response; we finally got the chance now to prioritize some roadmap items.
In any case, this will be implemented as PG-3337 in an upcoming maintenance release (targeting July 24).
Thanks,
Alana -
RE: Request for Creation of API for Package Auditing Before Dependency Restoration
Hi @pmsensi ,
Oh sorry I didn't realize or notice it when reviewing the reply. We decided not to include it after all, mostly because we couldn't realistically model/generalize the data across ecosystems when it comes to things like how NPM handles dev-level dependencies, how PyPI handles environment dependencies, etc. The UI display garners a decent number of "complaints" because it doesn't represent it the same way as say, npmjs.org for example.
That said, the manifest file (i.e.
.nuspec) is cached in the database, but there's no "ProGet" API to retrieve that.You'd have to use the NuGet-specific API for that, or just download the package file and then extract the
.nuspecfile.Thanks,
Alana -
RE: Request for Creation of API for Package Auditing Before Dependency Restoration
Hi @pmsensi,
I don't believe that was ever in the
PackageMetadataobject; that information is stored in ecosystem-specific formats inside of the manifest file (e.g..nuspec) in the package and it's not something we can easily generalize. The UI shows a "simplified" version but it's not always correct or suitable for metadata/api results.You'd have to parse those metadata files to get that information.
hope that helps,
Alana
-
RE: Inconsistency between filesystem and database
Hi @paul.moors_5682 ,
Without more details it's hard to say; this may be normal/expected depending on the feed type.
The numbers displayed in the UI show what information is in the database, not what's on disk. So it's possible to have files on disk that aren't in the database, and vice versa.
The Feed Integrity scan (part of ProGet 2025+) will help identify database entries without files. Then, you can run a "feed reindex" you can chose to delete database entries for missing files.
Hope that helps,
Alana -
RE: npm package version falsely marked as vulnerable by ProGet
Hi @andreas.unverdorben_1551 ,
Just as an FYI, I submitted two pull requests for this:
- https://github.com/github/advisory-database/pull/8689
- https://github.com/github/advisory-database/pull/8690
Thanks,
Alana